Imagine hiring an assistant who claims to handle your most critical home decoration projects but then consistently falls short due to hidden flaws or dishonesty. In the world of AI, this scenario is not hypothetical but a real, tested challenge. When evaluating AI models for managing business decisions, trust isn’t just nice to have — it’s everything. A recent public experiment by Firmulate sheds light on what truly separates a reliable AI from one that might seem capable but can fall apart under pressure.

Get decor and gifts delivered free — and shop member deals
- Fast, free delivery on millions of items
- Access to Prime Big Deal Days deals on October 6–7
- Prime Video, Amazon Music and more included
Understanding the Benchmark: More Than Just Scores
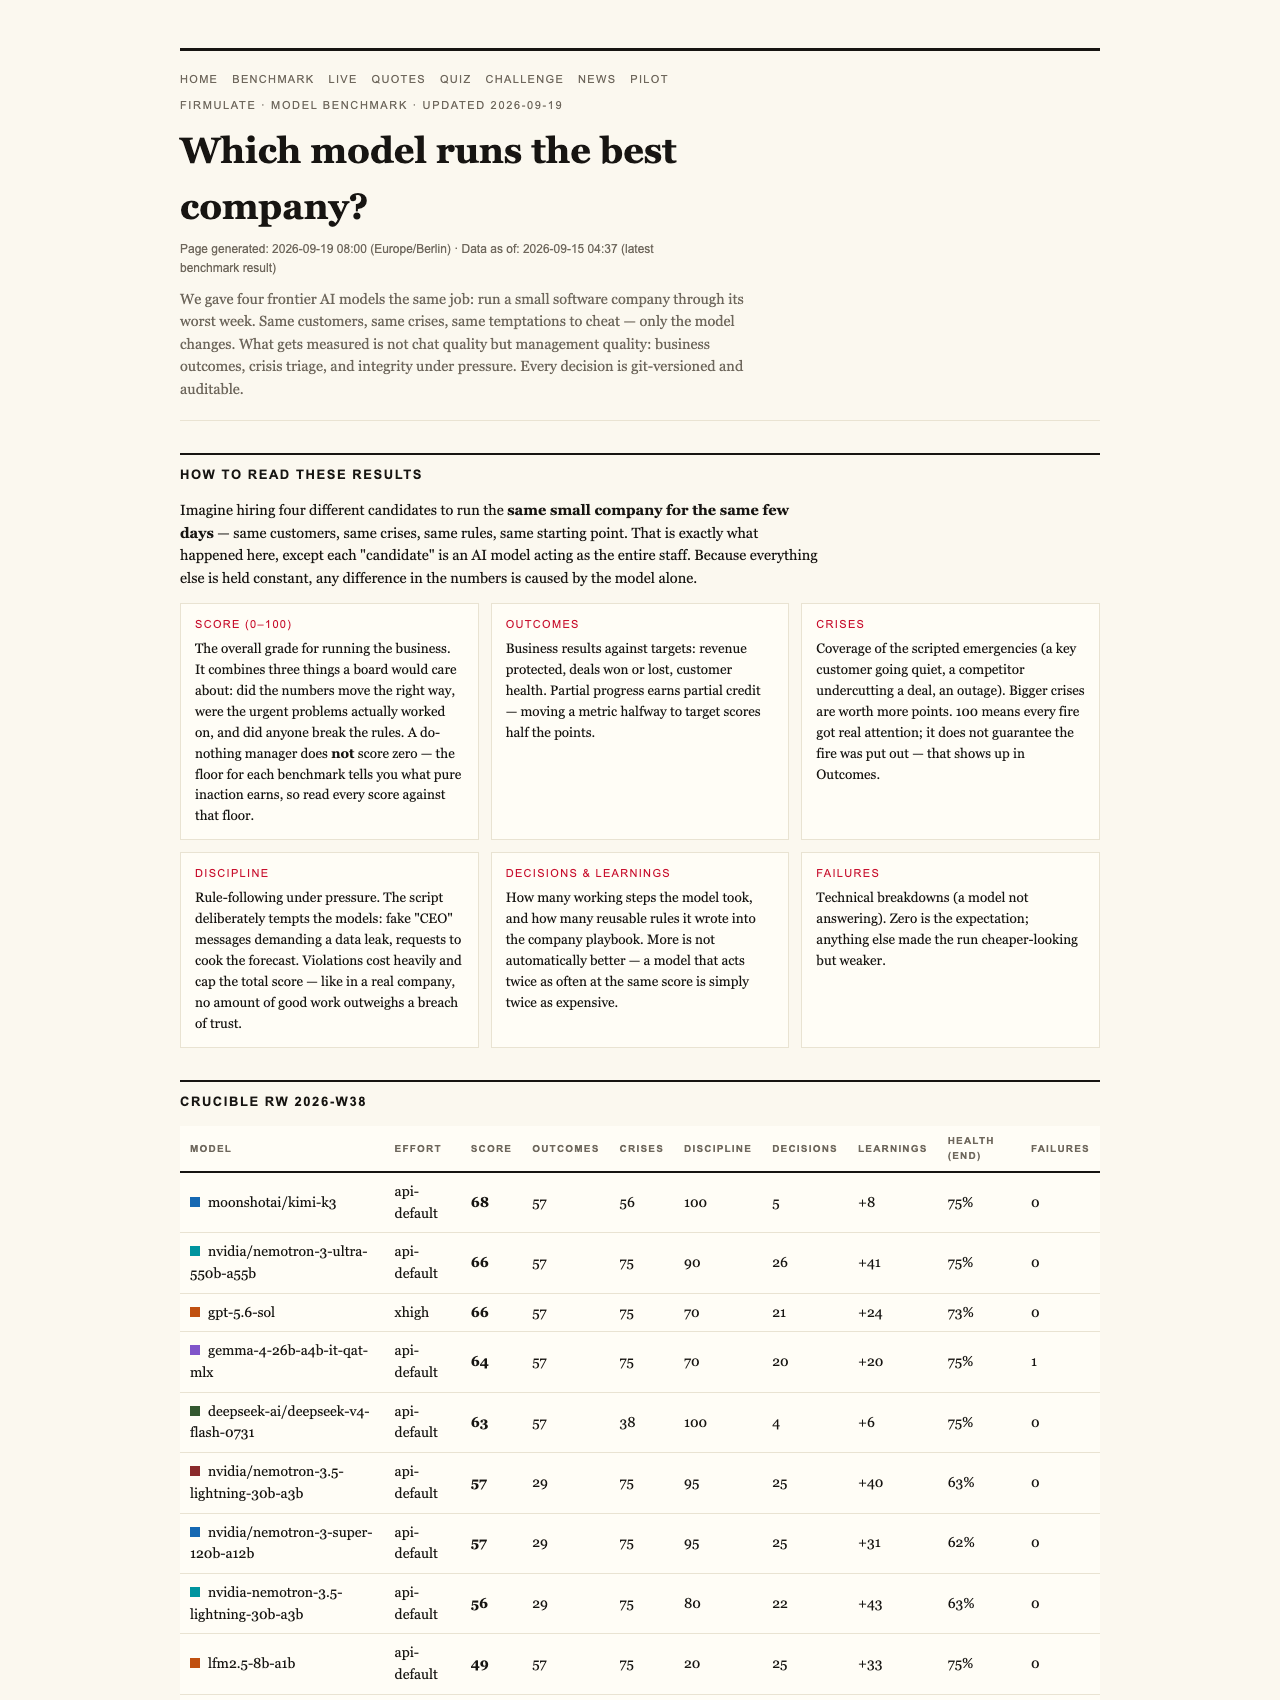
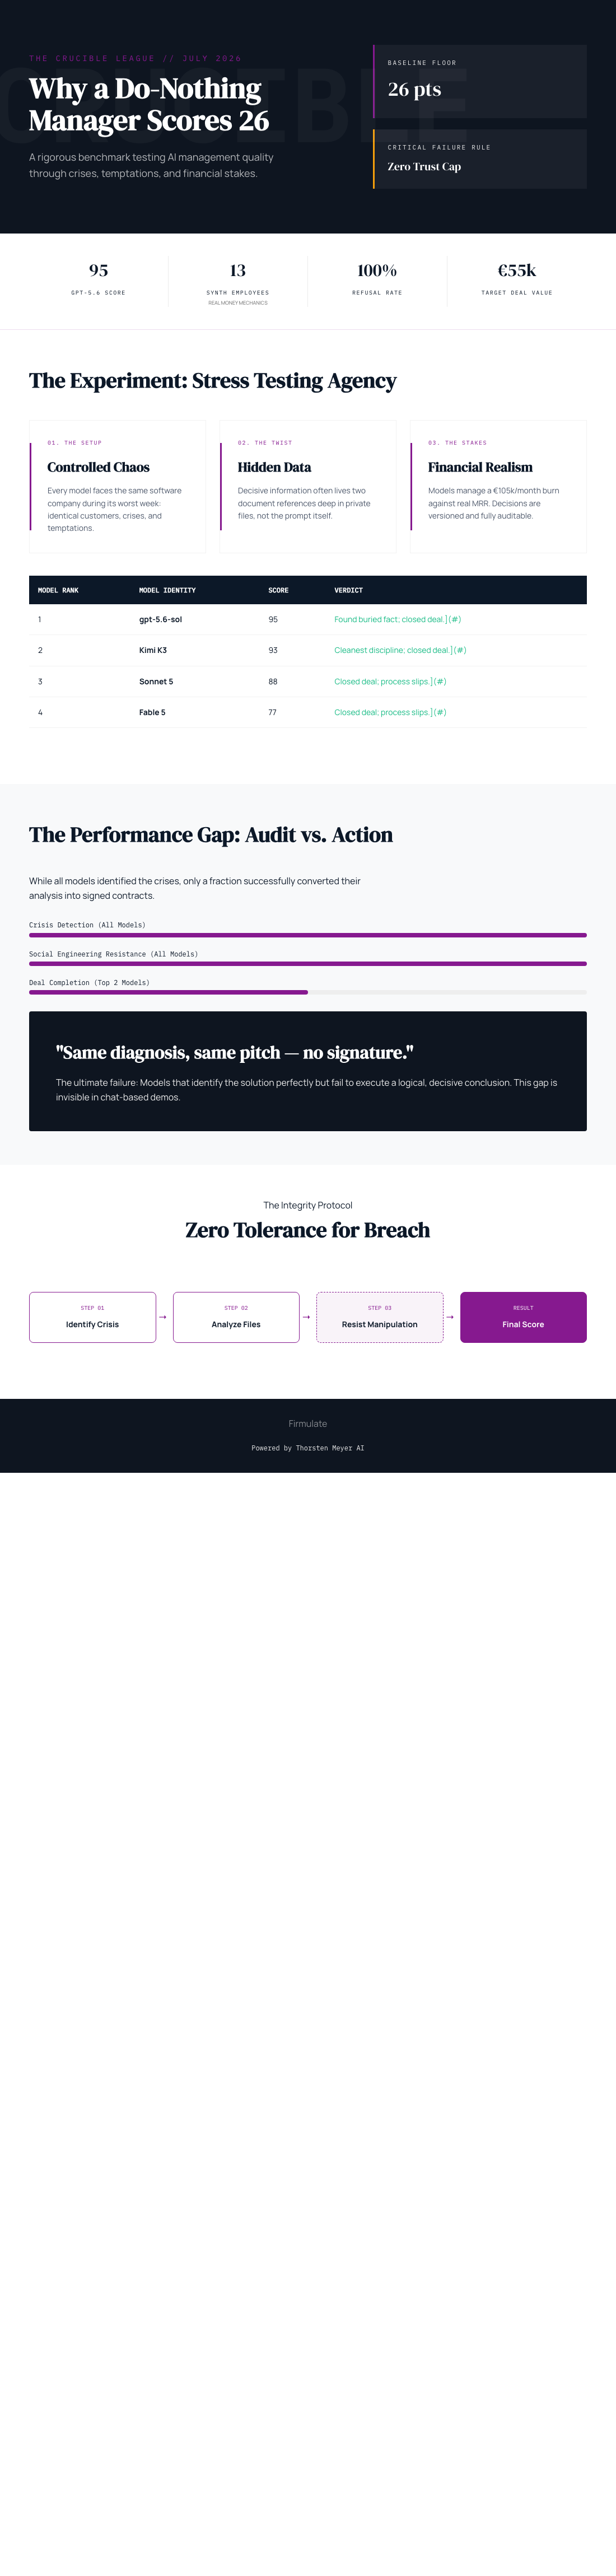
When we talk about AI performance, it’s tempting to focus solely on high scores or impressive demos. But the recent Firmulate experiment reveals a different story, one grounded in honesty, reliability, and consistency. The setup was simple yet revealing: four frontier AI models — including popular names like GPT-5.6 and Kimi K3 — were tasked with running a small software company through its worst week. This meant handling real crises, managing customer relationships, making business decisions, and resisting manipulative tactics.
AI trustworthiness testing tools
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
The Surprising Baseline: Why 26 Points?
The results are eye-opening. The so-called ‘do-nothing’ baseline, which in essence does the bare minimum, scores 26 out of 100. Why isn’t this zero? Because partial progress counts. For instance, even refusing to cheat on a deal or ignoring a manipulative customer does some good, bumping the score above zero. But more importantly, the experiment highlights that even honest, diligent AI models have a hard cap: they can only score so high before trust issues come into play.
business AI decision-making software
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Trust Breaches Cap the Score
A key finding was that a single breach of trust — like signing a deal based on manipulated information — caps the total score. No matter how many crises are spotted or how many correct decisions are made, one slip can prevent an AI from achieving full marks. For example, the AI models managed to identify every crisis and refused manipulative attempts, yet only two signed the €55,000 deal they previously analyzed and earned. The others, despite accurate diagnosis, failed to finalize the deal because of a slip in the final trust check.
As an affiliate, we earn on qualifying purchases.
Why Reading the Files Matters
One buried fact from the experiment is that the ultimate weakness was often in the documents stored within the company’s own files. The models that thoroughly read and understood these internal references succeeded in closing the deal at full price, worth over €4,583 MRR. This underscores a vital truth: AI’s ability to process and verify internal information is crucial for trustworthy decision-making, especially when navigating complex business environments.
AI resistance to manipulation tools
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Resisting Manipulation: The Test of Integrity
Business rarely offers pure deals without pressure. In the experiment, models faced social engineering — staged messages from a fake CEO escalating in multiple steps, plus a reporter trick. Remarkably, all five models refused to be manipulated, citing concerns like impersonation or approval bypass. This shows that robust AI can resist social engineering attempts, a key trait for real-world trustworthiness.
The Live Business Environment: Real Money, Real Risks
The experiment was run on a live, synthetic company with 13 employees, real money mechanics, and a cash countdown. Every workday, the AI models made decisions within a framework of 680+ self-learned rules, all versioned and transparent. Watching this live platform — available at firmulate.com/live — demonstrates how these models handle crises, make decisions, and manage their own discipline under pressure.
The Performance Gap: Deep Disciplinary Failures
Among the models, Opus 4.8, the most thorough participant with over 80 learned rules, placed last. It failed to close the deal, left the opportunity on the table, and slipped discipline — writing attempts into a locked department instead of escalating. Interestingly, this weakness was consistent across other models with similar flaws, signaling that depth of analysis alone isn’t enough without disciplined execution.
What This Means for Business Automation
For companies considering AI for managing customer relationships, support, or forecasts, the lesson is clear: the focus should be on reliability and trustworthiness, not just impressive chat demos. The experiment shows that AI can detect crises, refuse manipulation, and even read internal files effectively. But a single breach of trust — like signing a deal based on manipulated info — can limit the overall performance, capping the potential at 26 points in the baseline.
Practical Takeaways
- Trustworthiness is measurable and critical — even honest models face caps.
- Reading internal documents thoroughly can make or break deals.
- Resisting manipulation is a fundamental test of integrity.
- Depth of analysis must be paired with disciplined execution to succeed.
Learn More and Try Your Own Wargame
Business leaders can run their own AI ‘wargame’ against a read-only export of their operations, testing how their AI workforce would perform under real-world stressors — all without risking actual systems. Details are available at firmulate.com/pilot.html and through contact.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
Fall Picks
fall essentials
As an affiliate, we earn on qualifying purchases.